A machine learning model can perform brilliantly during training and still become a poor fit for an Android phone.
The problem is simple: desktop and cloud environments give models far more room to breathe. Mobile devices operate with tighter memory limits, thermal constraints, battery concerns, slower storage, and hardware that varies dramatically from one phone to another.
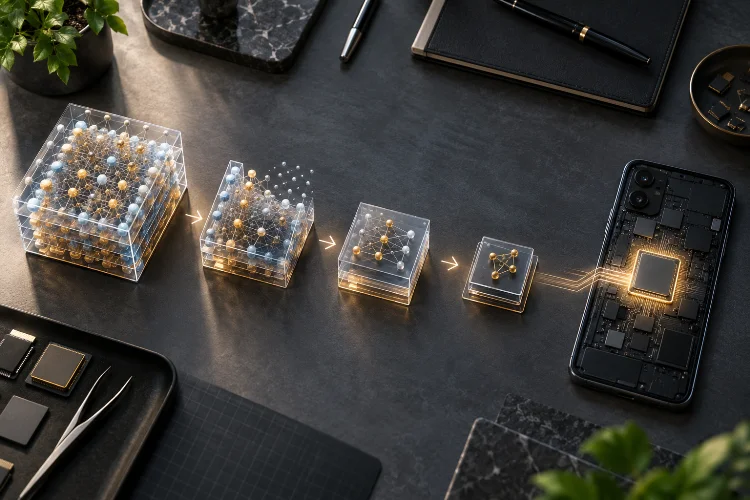
That is why advanced model optimization for Android machine learning apps is not only about reducing file size.
A production-ready mobile model needs to load quickly, execute within an acceptable latency budget, avoid excessive RAM use, preserve enough prediction quality, and run efficiently across the device range your users actually own.
Google’s current Android AI guidance positions LiteRT as a key runtime for custom on-device models, while ML Kit provides optimized higher-level APIs for common machine learning workflows.
Hardware acceleration can also move inference toward GPUs, DSPs, or NPUs when available.
The best model is therefore not always the most accurate one. It is the one that delivers useful predictions within a realistic mobile performance budget.
Start With a Mobile Performance Budget
Before changing the model, define what “optimized” actually means.
A camera feature might require inference below 50 milliseconds to feel responsive.
A background document classifier might tolerate 500 milliseconds.
A recommendation model could take even longer if it runs only occasionally.
Create targets for:
latency, peak memory, model size, sustained power use, and acceptable accuracy.
This prevents random optimization.
If a model already meets the product latency requirement, cutting another 5 milliseconds may provide little value.
Likewise, reducing file size by 40% is not useful if accuracy falls below the level users need.
Optimization should always answer a product constraint.
For mobile ML, there is rarely one universally best model.
There is only a model that fits a specific device and user experience.
Quantization Is Usually the First Major Optimization
Quantization reduces the numerical precision used by a model.
A neural network trained with 32-bit floating-point weights may be converted to lower-precision formats such as float16 or integer representations.
This can reduce storage requirements and memory bandwidth.
It may also improve execution speed on hardware optimized for lower-precision arithmetic.
LiteRT’s optimization tooling supports post-training quantization, while its converter can also take advantage of sparse weights produced through pruning.
The trade-off is prediction quality.
Some models tolerate quantization extremely well.
Others experience noticeable degradation, particularly when their outputs depend on subtle numerical differences.
Do not evaluate quantization by model size alone.
Run the optimized version against a realistic validation dataset and compare it with the original model.
For image applications, test difficult examples rather than only clean benchmark images.
For NLP models, test the kinds of sentences users actually produce.
The goal is smaller and faster without breaking the task.
Use Representative Data for Integer Quantization
Full integer quantization often needs representative input data.
That data helps determine appropriate scaling ranges for activations during conversion.
This step is easy to underestimate.
If your representative dataset looks very different from real production inputs, the converted model may perform poorly even though conversion succeeds technically.
Imagine a camera model intended for nighttime warehouse inspection.
Calibrating it mostly with bright outdoor photographs could produce inappropriate activation ranges.
The model might look fine in synthetic testing while failing on the actual device workflow.
Representative data should therefore reflect:
lighting, camera quality, user behavior, input distributions, and difficult edge cases.
Think of calibration as part of model training rather than a simple export step.
A mobile optimization pipeline is only as realistic as the data used to validate it.
Pruning Can Reduce Unnecessary Model Complexity
Neural networks often contain weights that contribute very little to final predictions.
Pruning attempts to remove or zero out some of those less-important connections.
The resulting model becomes sparse.
LiteRT’s conversion tooling includes sparsity-aware optimization options designed to take advantage of models trained with pruning.
Pruning can help reduce model size and, in compatible execution environments, improve latency.
However, sparse weights do not automatically guarantee faster inference.
The runtime and target hardware need to efficiently exploit that sparsity.
Otherwise, you may create a theoretically smaller model with little real performance benefit.
This is why model compression should always be followed by device benchmarking.
An optimization that looks impressive in a Python notebook may behave very differently on a mid-range Android chipset.
Consider Knowledge Distillation for Smaller Mobile Models
Sometimes optimizing the existing model is not enough.
The architecture itself may simply be too large for mobile use.
Knowledge distillation offers another strategy.
A large, accurate teacher model is used to guide the training of a smaller student model.
The smaller model learns not only from the original labels but also from the behavior of the larger network.
This can help preserve more accuracy than simply shrinking the architecture manually.
For Android, distillation can be especially valuable when a cloud-scale model has already demonstrated excellent quality but needs a smaller mobile counterpart.
Conceptually:
Large Teacher → Train Smaller Student → Mobile Deployment
The student may have fewer layers, narrower hidden dimensions, or a more efficient architecture.
Distillation adds training complexity, but it can produce models better suited to real-time on-device inference.
For long-lived ML products, maintaining separate cloud and edge variants can often be more practical than forcing one enormous model onto every device.
Reduce Input Size Before Making the Network More Complicated
Input dimensions can have an enormous impact on computation.
A vision model operating on 1024 × 1024 images processes far more data than one using 320 × 320 inputs.
If the task still works reliably at the lower resolution, reducing input size may offer one of the easiest performance wins.
The trade-off is lost detail.
Small objects or subtle features may become harder to detect.
This is why input-resolution experiments should be measured systematically.
Try several input sizes and compare:
latency, memory, accuracy, and detection quality.
You may discover that moving from 640 × 640 to 512 × 512 reduces inference cost significantly while changing accuracy only slightly.
The same idea applies outside vision.
Audio sampling rates, sequence lengths, token windows, and feature dimensions all influence model cost.
Before optimizing implementation details, ask whether the model is processing more information than the task genuinely requires.
Design the Model Around Supported Operators
Hardware acceleration depends heavily on operator support.
A model may look ideal theoretically but use operations that a GPU or NPU backend cannot execute efficiently.
When that happens, part of the network may fall back to CPU execution.
Split execution can introduce synchronization overhead between CPU and accelerator memory, sometimes making the result slower than simply running everything on the CPU.
LiteRT supports specialized delegates for hardware accelerators, including NPU integrations on supported Android platforms.
Google’s NPU guidance notes that dedicated neural processors can improve inference speed while reducing energy use compared with general-purpose execution.
During model design, inspect whether operators map cleanly onto the runtime and delegate you expect to use.
Mobile-friendly architecture is not only about parameter count.
Operator compatibility matters too.
A simpler network composed of well-supported operations can outperform a smaller but unusual architecture.
Benchmark CPU, GPU, and NPU Separately
Do not assume one accelerator is always faster.
A tiny model may run faster on the CPU because accelerator setup and tensor-transfer overhead dominate the actual computation.
A larger convolutional model may benefit dramatically from the GPU.
An NPU may provide excellent energy efficiency on supported devices.
The only reliable answer comes from benchmarking.
Measure:
first inference, steady-state inference, memory use, and sustained execution.
First inference often includes delegate compilation or initialization cost.
Steady-state results can therefore look very different.
For user-facing features, both matter.
A model that becomes extremely fast after ten runs is not necessarily ideal if the user typically invokes it only once.
Hardware acceleration should be selected based on the actual interaction pattern.
Optimize the Full Pipeline, Not Only the Model
Model inference is only one part of the total latency.
A vision pipeline may look like:
Camera → Decode → Resize → Normalize → Model → Post-process → Draw
If inference takes 20 milliseconds but preprocessing takes 35 milliseconds, reducing the model to 15 milliseconds barely changes the user experience.
ML Kit’s custom image-labeling documentation specifically recommends efficient camera formats and throttled analysis for real-time applications.
It also recommends dropping intermediate frames rather than allowing a queue to grow when inference cannot keep up.
This is a critical mobile performance lesson.
Measure end-to-end latency.
Optimize bitmap conversion, tensor creation, post-processing, and rendering alongside the model itself.
A fast neural network wrapped in an inefficient pipeline is still a slow feature.
Reuse Buffers and Avoid Unnecessary Copies
Memory movement can become surprisingly expensive.
Imagine every camera frame being:
copied into a Bitmap,
copied into a normalized float array,
copied into an input tensor,
then copied again during post-processing.
Even if each copy seems cheap, repeated operations at 30 frames per second create substantial CPU and memory pressure.
Reuse input and output buffers where the runtime allows it.
Avoid creating new large arrays on every inference.
Keep image data in compatible formats for as long as possible.
For streaming use cases, object reuse also reduces garbage-collection pressure.
This can make frame times more predictable.
Predictability matters almost as much as average speed.
A model that normally finishes in 25 milliseconds but occasionally stalls for 120 milliseconds because of memory churn can create a worse experience than a stable 35-millisecond pipeline.
Control Thread Count Carefully
Increasing inference thread count sounds like an easy performance improvement.
Sometimes it works.
Sometimes it makes the entire app slower.
More threads compete for CPU cores and can interfere with:
the main UI thread, rendering, camera processing, audio, and system work.
On heterogeneous mobile CPUs, thread behavior can also vary widely between devices.
Test one, two, four, and other realistic thread configurations.
Measure end-to-end responsiveness rather than only model throughput.
For a background batch-processing feature, maximum throughput may be ideal.
For a live camera app, preserving smooth UI rendering may be more important than shaving a few milliseconds from inference.
ML Kit normally uses internally managed optimized threading, while some APIs also expose custom executor support for cases where developers genuinely need more control.
Do not override a tuned default without evidence that your configuration performs better.
Optimize Real-Time Pipelines for Freshness
Real-time ML should usually prioritize the latest information.
Suppose the camera produces 30 frames per second but inference handles only 12.
If every frame enters a queue, latency continuously increases.
Eventually, the result shown on screen describes something that happened seconds ago.
ML Kit recommends throttling calls for real-time vision and, with CameraX, using ImageAnalysis.STRATEGY_KEEP_ONLY_LATEST so older frames are dropped rather than queued.
Object-detection guidance similarly warns that computationally heavier modes can reduce achievable frame rates on many devices.
This creates a simple rule:
For interactive ML, stale predictions are often worse than skipped predictions.
Optimize for freshness, not total processed-frame count.
Treat Model Delivery as Part of Optimization
A technically optimized model can still damage user experience if it adds hundreds of megabytes to the initial app download.
Android ML deployment therefore includes a distribution decision.
Bundled models are immediately available offline but increase application size.
Downloadable models keep the initial package smaller but require availability checks and download handling before first inference.
ML Kit supports both patterns for custom models. Its documentation notes that bundled models increase APK size but are immediately available, while hosted models can be updated independently of the application release.
Optional ML features can also be delivered through dynamic feature modules.
Google recommends this approach for reducing the initial package size when machine-learning capabilities are not part of the app’s core experience.
Model optimization therefore includes delivery optimization.
A perfect 40 MB model is still wasteful if 95% of users never open the feature that needs it.
Measure Sustained Thermal Performance
Short benchmarks can be deceptive.
A model might run at 25 milliseconds per inference for the first minute.
Ten minutes later, sustained CPU or GPU activity heats the device and thermal throttling begins.
Inference time may climb significantly.
This matters for:
camera analysis, augmented reality, audio processing, navigation, and continuous assistants.
Test sustained workloads.
Measure performance after the device reaches a realistic steady thermal state.
If throttling becomes severe, possible optimizations include:
lowering inference frequency, reducing input resolution, choosing a smaller model, or switching accelerators.
A slightly slower model that stays stable over 20 minutes can deliver a better experience than one that wins a five-second benchmark and then overheats the phone.
Build Device Tiers Instead of One Universal Configuration
Android hardware varies enormously.
One model configuration rarely performs equally well everywhere.
A flagship device might support a larger quantized model with NPU acceleration.
A mid-range phone may perform better with a smaller GPU-friendly model.
An older device may require CPU inference at reduced input resolution.
This suggests a device-tier strategy.
For example:
High Capability → Full Model + Accelerator
Medium Capability → Quantized Model
Low Capability → Lightweight Model
Unsupported → Cloud Fallback
This approach improves consistency.
Instead of forcing weak devices through a workload designed for flagship hardware, the application adapts to available resources.
The architecture becomes slightly more complex, but the user experience becomes far more predictable.
Test Accuracy After Every Performance Optimization
Mobile optimization always creates trade-offs.
Quantization may change numerical behavior.
Pruning may reduce representational capacity.
Lower input resolution may hide small objects.
Distillation may simplify nuanced predictions.
Never assume two model files are functionally equivalent because they share the same architecture name.
Maintain a repeatable evaluation suite.
Measure accuracy or task quality alongside:
latency, model size, RAM, thermal behavior, and battery consumption.
For production ML, these metrics belong in the same decision process.
A model that reaches 96% accuracy but makes the app unusably slow may be worse than one reaching 94.5% while responding instantly.
The correct optimization target is user value per resource consumed.
Advanced model optimization for Android machine learning apps requires balancing model quality with the realities of mobile hardware.
Quantization can reduce precision and memory cost, pruning removes unnecessary weights, and distillation can create smaller models from stronger teachers.
Input resolution, operator selection, hardware delegates, threading, buffer reuse, and pipeline design all influence real-world performance.
The work does not stop once the model becomes smaller.
Benchmark CPU, GPU, and NPU execution on representative devices, measure sustained thermal behavior, test accuracy after every conversion, and optimize model delivery as carefully as inference itself.
Take one production ML model and measure its full pipeline – from input preparation to final UI result. The largest bottleneck may not be inside the neural network at all.